English
 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek
Breaking: UK Workforce Management Market Set for Significant Expansion
Networking |
2026-10-07 07:15:36
Defining the Core of Big Data Infrastructure
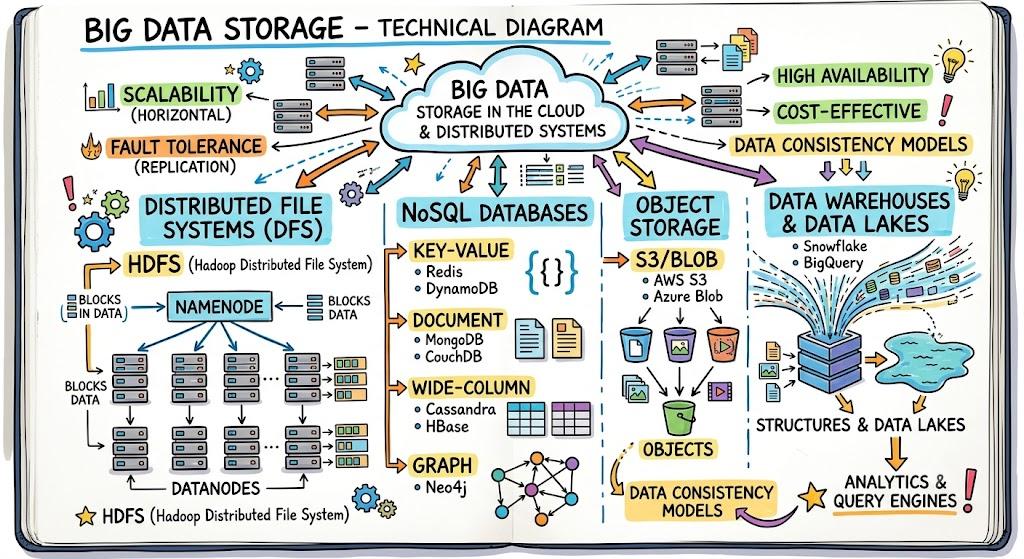
In the context of modern IT, the term "platform" signifies more than just a single product; it represents an integrated and foundational environment upon which other applications and services are built. A Storage In Big Data Market Platform is precisely this: the architectural blueprint for housing, managing, and accessing vast quantities of diverse data. It is not simply a collection of disks but a cohesive system of hardware and software designed to provide scalability, durability, and accessibility for data at petabyte scale and beyond. The primary goal of such a platform is to create a centralized, reliable, and cost-effective repository that can serve as a "single source of truth" for an organization's data assets. This platform must be flexible enough to handle structured, semi-structured, and unstructured data, and performant enough to support a wide range of workloads, from traditional business intelligence and reporting to high-performance data science and machine learning. The design and implementation of this storage platform is one of the most critical decisions in any big data initiative, as it directly impacts cost, performance, and the overall ability of an organization to derive value from its data.
The Data Lake: The De Facto Platform for Unstructured Data
The most prevalent architectural pattern for a big data storage platform is the data lake. A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale. Unlike a traditional data warehouse, which requires data to be cleaned, structured, and transformed before it is loaded (a process known as schema-on-write), a data lake allows you to load raw data in its native format (schema-on-read). This flexibility is its greatest strength. The foundational technology for most modern data lake platforms is object storage. Cloud services like Amazon S3, Azure Blob Storage, and Google Cloud Storage are the prime examples. Object storage is massively scalable, highly durable, and extremely cost-effective, making it the perfect platform for storing petabytes of data. It treats data as objects, each comprising the data itself, a variable amount of metadata, and a globally unique identifier. This simple, flat structure allows for near-infinite scalability and makes it easy to store diverse data types like images, videos, log files, and sensor data. The data lake, built on an object storage platform, has become the standard starting point for big data analytics and AI/ML projects.
Software-Defined Storage (SDS): The Platform of Flexibility
Another critical platform concept shaping the market is Software-Defined Storage (SDS). SDS is an architectural approach that decouples the storage management software (the control plane) from the underlying physical hardware (the data plane). In a traditional storage array, the software and hardware are tightly integrated and sold as a single package by one vendor. SDS platforms break this lock-in. The SDS software can be installed on commodity, off-the-shelf server hardware from any vendor, turning it into a sophisticated, feature-rich storage system. This provides organizations with immense flexibility and helps to avoid being tied to a single hardware provider. SDS platforms offer many of the advanced features found in high-end arrays, such as thin provisioning, snapshots, replication, and data tiering. They are particularly well-suited for building large-scale private cloud environments and managing storage for virtualized workloads. By abstracting the intelligence into software, SDS platforms provide a unified way to manage diverse hardware resources, simplify administration, and enable a more agile, scalable, and cost-effective storage infrastructure, making it a key platform choice for modern data centers.
The Rise of Unified Data Platforms
The line between storage and compute is blurring, leading to the rise of unified data platforms that seek to provide a single, integrated environment for both. Platforms like Snowflake and Databricks are prime examples of this trend. While often categorized as data warehouse or analytics platforms, they have a profound impact on storage strategy. Snowflake, for instance, pioneered the architecture of separating storage from compute in the cloud. It allows customers to store all their data in a central repository (typically on a cloud provider's object storage like S3) and then spin up independent compute clusters of various sizes to run queries against that data. This architectural platform provides incredible elasticity. Similarly, Databricks' "Lakehouse" platform is built on top of open data lake storage and open data formats like Apache Parquet and Delta Lake. It provides a unified platform for data engineering, data science, and machine learning workloads to all work on the same copy of the data in the data lake. These platforms influence the storage market by strongly promoting the use of open, cloud-native object storage as the central data repository and by demonstrating the power of decoupling storage and compute for maximum flexibility and cost-efficiency.
The Future Platform: A Hybrid, Multi-Cloud Data Fabric
The ultimate future of the storage platform is not confined to a single location or a single vendor. It is evolving into a "data fabric"—a distributed, intelligent, and unified platform that spans on-premise data centers and multiple public clouds. The goal of a data fabric is to provide a consistent set of data services and a single management interface for all of an organization's data, regardless of where it physically resides. This platform would abstract away the underlying complexities of different cloud providers and on-premise hardware. Key features of this future platform will include global data mobility, allowing for the seamless movement of data between locations based on cost, performance, or compliance needs. It will incorporate a global namespace, so applications can access data without needing to know its physical location. It will also enforce consistent data governance and security policies across the entire hybrid environment. Vendors are actively building the components of this platform today, with tools for multi-cloud data management and hybrid cloud storage solutions. This vision of a unified, intelligent data fabric represents the next frontier in big data storage, promising to finally tame the complexity of a distributed data world.
➤ Featured Insights from Market Research Future: